
From Assistants to Agents: Self-Improving Agentic Systems with Spring AI by Christian Tzolov
About this talk
This talk explores the use of Spring AI to harness the capabilities of large language models (LLMs) in application development. The speaker discusses the black box nature of LLMs, emphasizing their statelessness and the importance of managing conversation history for effective interactions. By implementing concepts such as memory advisors and context injection, developers can enhance the functionality of their applications. The session covers various architectural patterns, including retrieval-augmented generation (RAG) and structured output responses, to guide LLM behavior. Additionally, advanced techniques are presented, such as tool calling and the use of sub-agents to manage complex tasks efficiently. Overall, the talk illustrates how to integrate various Spring AI capabilities to maximize LLM performance.
Full transcript
[music] >> Good afternoon, everyone. Great to be around. I assume how many of you have used Spring AI? So, I guess so, almost everyone. Cool. We're going to talk about how very few very small concept actually can help you build almost any any complex genetic pattern out of it. So, and if you start with very simple use case, everyone of you have familiar, you're going to pass
and use LLM, you're going to send the context, get some feedback, try to improve it, and loop over until you get the response that you expect to be useful for you. And it's kind of a relentless loop to to get there. And I'm kind of I really like this blog post by Raphael few days back or last last week where not many people may maybe everyone now
realize that when we talk about generative AI, it's not really about training model or using it's more like how to use this model like a black box or like something that you can use its intelligence. It's very useful, but how can actually we can make use of it in our system to provide the proper validation, proper quality. Quiet. Be quiet. >> [laughter] >> And so, if we're
about to talk about how to use this black box in our systems, it's it really helps to understand what those black box are actually. What are the important characteristics of this black box? Statelessness is one of the most important bits. Also, those models have been pre-trained up to some point in the past. Uh that's another important thing so we have to consider. Text in, text out, non-structured
response, and they're non-deterministic, which is good, they're creative, but also they can be hallucinating, which is not that good. And finally, it's very important to to to realize that we have a limited amount of data that we can get in and get out in a single pass, single turn. And it's measured in tokens. So, having this in mind, and we mentioned it's stateless, how we're going to
build a stateful application or maintain state in your conversation? Again, it's straightforward when you start looking into this black box part, you have to intercept your communication to the LLM, put append the the question to some sort of memory storage, and send to LLM not the question itself, but the question user question along with some pre-preset of history from the previous conversations, you will subset of this,
and you should also intercept the output and put it into append it into the conversation history or memory in order to enable the follow-up conversation and to support this. So, if you look into this, it is this intercepting the input and the output of your black box, and this is the typical concept of interceptor or or advisor or hooks you can think of. It's a nothing new
or filters if you're coming from the web background. And this is how we're doing it Spring. You have this concept of advisor or interceptor that allows you to intercept and augment what gets into the LLM and what gets out of the LLM. And this is the typical implementation of the chat memory advisor. And having this I intended to show actually the new session ID implementation. We have
a new stuff that we have just starting incubating and preparing. Maybe I will show the demo or but it's the same principle underneath. Simply it's like a different implementation. And this is indeed the general concept of advisor. It's the most powerful bit that you should forget memorize from this conversation because we're going to build almost everything on top of this simple concept from now on. Uh so,
again, we have the ability advisor which is this piece of code that you can put on the path of your interaction with the LLM in and out, and it allows you to augment the input and output of your LLMs. Uh on your of the information that gets in and gets out of the LLM. So, let's look into another use case that maybe this would be useful as
well. How actually can make the LLM answer question that are relevant to some recent domain or something that is your that's relevant to your particular enterprise. And this always falls into this context of this group of context stuffing or RAG general pattern, which on the surface means something looks something like this. Your user user ask question that is not known to the LLM. LLM has been pre-trained
some to some point in time in the past. So, you are supposed to pass some additional context that would inform the LLM how to answer your question in the this particular domain of knowledge that you want to to to to ask the LLM to provide you with support for. And the typical ways to do this is to either inject the entire uh static files or static information
if you can fit it in the context. Again, we have to be mindful mindful that we have pass in and out. Or you're going to use one general concept where you're going to preload this information you're interested into external storages. It could be regular databases, graph databases, full text search, or most common cases is semantic search base system where it's vector store embedding. This is not again
the purpose of this discussion today. Here is the guy Thomas Vitali who contributed very advanced Yeah, don't don't Yeah, you're here. So, who contributed very advanced model RAG support for Spring AI. What what is interesting to stress out here is the the way to handle this under the service again the same pattern. We are intercepting the input and practically how it works and the user the user
input is actually passed and we use the user input as a query to figure out what are the most similar chunks or or entries in the our existing vector databases and retrieve those and stack it in our context on the way to ask the LLM. Another interesting point which return to later on, we're doing this injection or stuffing up front before consulting the LLM. We are trying
to be smart. We're trying to figure out what is the most important piece of information related this context judging only by the user question. In some advanced case, it can actually escalate elevate this bit, but the principle is the same. We are doing this without consulting the LLM. It's not agentic in that sense. Another class of problem is again the LLMs are the LLMs are not deterministic,
so they're not predictable. And the most common way to try to to to control them is to put some boundary in the input and output. This is falling in the in in in the realm of guardrails. Practically, you're going to implement some sort of logic before you send the the message to LLM, or you're going to put some sort of logic that would decide whether you're going
to forward the response to your customer or not if the LLM have provided a satisfying response. So, very quick example, how are you going to do this? You imply this pattern if you want to provide some sort of sensitive words protections. You would like to prevent sending sensitive words to your LLM assuming that maybe or it could be sensitive words or it could be passwords or some
some additional information that that should not get out of the realm of your enterprise or your company. Very straightforward, and this is very simplistic example. Let's Let's me go. And I forgot guys to to show you all the demos along these bits. That was the main purpose of this question, but I would walk you through. So, the chat memory. And this would give you some We discussed
about the chat memory. Everything you have to do is to put this memory advisor in your path. So, without if you try to So, what we're doing, we have chat client. We we ask introduce ourselves, and we ask what our name is. the responses would be I don't know. Which makes sense, it's stateless. If we plug this Anyway, all those examples most of you have used chat
client already. I presume they're pretty you're pretty pretty familiar with this concept. I would kind of rush because there is much more interesting high-level abstraction that I would like to cover. But now, yeah, it knows my name. Similarly, I introduced the concept of RAG, and this is the naive RAG implementation. In this case, I'm practically injecting some additional information. This is some information for some I don't
know on Wikipedia. Normally, you're going to preload this offline, and at turn time, you are going to use this advisor that is going to perform the RAG for you. So, that everything that you have to do is And there is a different implementation. This is the most naive one. And this question would be answered with information that is additionally injected from this advisor. We can even see
that uh what you see in in in in yellow yellowish color here is practically another advisor that intercepted the input and output and put prints out some input important information to help us understand. So, we send this to the advisor. So, apparently the RAG injected some additional context. Yeah. And then we got relevant information back. The I covered the I I have covered the simple advisor even
going to to skip this example because there is much more interesting example about another guardrails. So, this one is just asking checking if the contents has some sensitive words. If not, the the question is going to be forwarded to the context. If yes, it's there is actually something sensitive and detected this this communication is going to be abandoned. But let's see something much more useful. Guardrails, when
you want to actually interrupt and check something about the output of the LLM. And Spring AI has been supporting structured response. This is another limitation of the LLM, the text in text out, unstructured. But with Spring AI, you can support structured in enforce structured response on different levels. The most simple one to do it, and actually what how it works under the cover. Let's say that the
user instead of simple text asked the response that is in certain type format. The Spring AI is going to convert this type into a JSON schema, automatically inject it into your again augment, intercept your input, augment your context, and ask LLM politely to actually provide the response into this particular format. Uh most of the time, LLM is going to provide the response in this format. You're going
to convert it and send it back to the user. What would happen if Uh and yeah, in this 1% where actually the LLM do does not provide the right format. If this happens, let's say 1% of 100, one time of 100. And what would happen, the user is going to see error a message itself. And it has to have it would be some conversion error. So, this
JSON actually doesn't comply with the schema. We're trying to convert it, and it would fail. So, how we can solve this with using now this concept of advisors? It's yet an another advisor you can plug on our path. And it this case in this time, it actually it intercept the output. And the output is here it checks whether the text is compliant with the schema that we
would want to validate. everything's good. We can go forward. If not, we're going to just send And this is interesting bit. We're going to send back additional feedback information, put it in the context, and ask the LLM again. And most of the time, second attempt is successful. And what's more important is that this actually is happening without the involvement user explicitly. So, let's see how this looking
code. Actually, Spring AI provides this advisor out of the box. It's called structured output advisor. And what we want to achieve here, we have this actor films. This is our desired type. And this is how we Spring AI was saying quite with instead of text response, please provide the response that is compliant into this format. And we're asking generate the filmography of five moves by Tom Hanks
for Tom Hanks. What is happening here, actually two interesting bits. First, this is a new addition to the Spring 2.0. You can opt for the structured output native format. Many of the AI models nowadays and APIs for these models, they started to provide this capability of structured output built in into their APIs. So, in Spring AI trying to be a portable abstraction across all these different providers,
if the provider support AI provide support these capabilities, and you have enabled this feature, it is going to often try to use and ask the API's feature for this structured response. If it's not available there, it is going to fall back to this general behavior that I have showed it in in 99% of the cases, it's still going to fulfill this capability. But in either case, if
the response is not compliant with the schema, this would be a error message. So, what you can do in addition is inject this advisor, as I showed earlier, and this should be enough to provide the response into the structured to ensure that And you can configure it how many of times you need to do, but the important thing is that Okay, this is the wrong demo. Run
this guy. Um Again, the idea here idea here I'm trying to to implant and to to to suggest here is the structured response that we're using over and over the same kind of approach to how either handling the input and output. And what is interesting here is that we have actually this feedback line. You have this loop that goes back. So, it's an advisor that actually does
something extra. And when you want if you want to extend on this approach, this is another advisor. While this one actually the previous one had kind of deterministic logic to check what is the output, this uses LLM. It it does again guardrails on the checks the the gate out. But actually, you can use another LLM to check the correctness of the the response for the first one
and make some action. So, in this case, you can check that's very common things. Does this response complies or or answers the original user questions? So, the judge LLM say yes or no. Usually, some writing there is a structured response to do these bits. If yes, we are you're happy you're going to send the response back to the user. If not, the the judge LLM is going
to provide additional information that we're going to inject into the original context along with the original context and try to improve the response again. And again, this is something that can happen as a loop automatically while actually do it you're trying to improve. And there's different way to do this this implementation. Most of the time, you're going to use a dedicated smaller fine-tuned judge LLMs, which are
trying to not be that biased and can support ranges. Uh Hugging Hugging Face actually provides a live board that you can use to export this to select such models. In code, it would be yet another advisor that you're plugging into your pipeline. And this is interesting example. I deliberately have a tool that return And I'm running a little bit out of time, but everyone knows what tools
is, I guess. So, we're registering a tool that provide real-time weather information. I deliberately um uh um I'm going to generate kind of not realistic information uh for two thirds of the cases. And I have this self-refined advisor that is staying in our loop. And we're going to run this to see how it looks. Okay. We were lucky. We have a negative temperature. Now, I assume that
the advisor uh the the judge LLM is going to detect this response. And before actually returning to the user, it is going to try again. Okay, even the second attempt was unsuccessful. Hopefully, the third one would be successful. No. And because we have only I think Yeah, only three attempts, it failed. I can run it again, but um if it's successful, it what would happen. But you
get the idea. So, practically, it's trying and it's doing all this on behind. You What you are paying as a user, it's additional latency and more more loops that go back and head. But anyway, if you want to implement this to handle this situation, you would have to do it yourself in your own code. So, this is just um easy way to plug this behavior as an
advisor into our path. And practically, another interesting story, in the past when we started Spring AI in 3 years ago, we were discussing about prompt engineering. That was the big thing. Over time, it was realized it's not about the text. It's about the whole metadata that gets to the the model. So, we started to talk about context engineering. And now the new hype is harnessing. Agent harnessing
stuff. And what is harnessing, no one can tell you, but that can tell you what is not. And the best definition I've heard it, everything that's not the LLM is harnessing. So, officially, Spring AI is a harnessing framework as well. So, everything I can build in order to provide useful information use the LLM for some purpose is a harnessing as this And the advisor is very elegant
way that you can provide harnessing logic into your existing pipelines. Again, this is the interesting bit. So, we have this advisor that allows you to return some feedback back to the user, back back to the original context and Tool calling Tool calling is another example that can be implemented as a advisor, and it should be implemented as advisor. Historically, it was in Spring AI it was implemented
in very low layer layer into the chat model, which made it almost impossible to perceive and observe what's going on there. So, we always had this problem and intention. I would like to have this hook. I have to have And we had a lot of bits which only signify that it was a wrong place to implement this logic. And when you think on along all these ideas
that I shared so so far, it makes perfectly sense to implement the tool calling as yet another advisor. And what tool calling is for those that are not familiar, it's one of the most This may be the second In addition to advisor, this is the second important concept that you should take away from is that most of the foundational LLM nowadays, they've been pre-trained to recognize that
if you push put some additional information a metadata in your context like, I by the way have these functions, these tools that can provide you with additional information if you're interested, the LLM can use the opportunity. And if it needs it for particular task, can instead of providing the final response, it can send us a special message say, "Oh, by the way, can you actually call this
function that you have?" For example, if you have real-time weather forecast, this metadata would be like my I have tool called real-time weather. The description, which is very important part of the tool definition, is that hint for the LLM when it should use this tool if necessary. So, this can be as simple as real-time information weather And then the third parameter usually in the metadata is what
are the parameter types that this function takes. Often expressed as a JSON schema. So, with all this information, LLM can actually decide for particular case to go back and ask for additional information. Spring AI provide the plumbing, and this is exactly the the logic I was talking about. It would intercept, dispatch this special message for tool calling, know how to find the right tools, call it, get
the information, augment the original context, and try and pass this information to LLM to in order to answer the the questions. And indeed, this is how it's going to look if you're using the same concept of I was about to say harnessing, which is the same, but advisors. So, you're intercepting the output. You check if the output message is not the normal response, but it's a tool
calling message. You And then implement the same logic. You're dispatching them. You're using tool call manager, access the response, and put it in your context. So, this is interesting bits you the tool call advisor was supposed to support to support some sort of mini memory or conversation history. And I'm mentioning this because when you start to mixing and matching and combining multiple advisors like memory and tool
calling, you have to be mindful about detail. there is an example, but let's Okay, the example is very straightforward. Just let me show how it looks in code. We already used with the previous example the the concept of tools because we called the weather, but here is more realistic one. There is different ways in Spring you can define the tools. It could be as simple as Java
tool functions. The most common way though is to annotate some methods with a tools. If you use MCP, it would be MCP tools, but the principle is is the same. We're going to indicate to the Spring framework that this is supposed to be a tool. A Spring framework is going to take care to convert this into tool description, know how to find and call this tool, and
that's in place. So, in this case we're using the real weather third-party application to get information, and we can ask question like, "What should I wear today in Amsterdam Barcelona?" I live nearby Amsterdam. And the response we expect we're asking for two really different locations. So, I would expect that there will be two calls. Indeed, two get temperature calls with the different parameters. We That's what we
asked. That's what the the assistant replied to us. This with this tool call request, then the user and the Spring AI dispatched this, resolved, found the right temperature, and returned it back to the model. So, this is the the dance. Again, the focus is not that much about how tool calling works. It's about that we're using the same principle to implement these capabilities. And when we start
to talk about this, allow us to enable much more advanced interesting patterns like tool search tool. If you have used If you have used MCP servers, it's very easy to overload your system with only tool definition. This bits here can very easily be populated if you have 100 tools or few hundred tools, and that's very common. If you just use only the GitHub MCP server, you'll end
up with a few hundred tools. Then it's it's very difficult for the LLM to dispatch which tool to use. And also you're wasting a lot of context because you're passing back and forth practically back a lot of information and metadata that mean you might not ever ever need to use. So, how you can solve this problem? Historically, people have been trying to use rag like techniques using
the user question to pre-filter what are the tools that might be necessary for this user question, but it turns out that this is very weak approach because the user question itself might not indicate or the intent that and the the real intent that necessary to provide just a semantic search is not enough as a mechanism to to understand the intent of the user message in order to
figure out what are the tools that are responsible. So, what you should do and what actually the tool call calling is very powerful, you're delegating this responsibility to the LLM. From the user question, the LLM much better can actually figure out what are the tools and what is the real intent and the real task that needs to be performed in order would be needed to to perform
this task. And now going to the tool search tool, and this is coming into this general pattern of progressive disclosure data disclosure. I call this progressive tool disclosure. The idea is very simple, but very powerful. Instead of sending all these hundred or few hundred or even thousand tools in your metadata in your single request every every one and each of your request to the LLM, you're going
to register a single tool called tool search tool that has definition If you need some additional information, practically informing this LLM that if it needs it needs some additional information, it can actually go back to us and ask for this information for this to to be registered on runtime. And at same time, when we start the application, we are indexing all our available tool on the client
side in some sort of tool searchers, and there is a different implementation that still can use semantic search with vector stores, Lucene, even regular expression as simple as those. And now the LLM, let's say we have the same example. We have thousand of service thousand of tools, and one of them is the real-time weather forecast information. And if we ask the same question, the LLM would come
back first and "And do you have practically a tools that provide this real-time information?" We're going to retrieve the best matches that we have in our searchers, register them to LLM, and now the LLM can actually ask this question. I have very nice demo that illustrates this uh in practice. And it's very powerful pattern. We're going to make it part of the release 2.0 coming next month
of Spring AI. So, right now it's part of the Spring AI community. You already can use it, but feel free to give it a try. Okay, here is the demo. And in order to try to simulate what might look like, I have few good functions tools. The question I'm going to ask, "Help me plan what to wear today in Landsmeer." This is a town in the Netherlands.
And then I have this Okay, what's important? Please suggest clothing shop that are open right now in the area. So, the time is involved as well. So, I'm providing a tool that can provide a real-time current time, then a weather that provides the weather forecast, but also weather forecast for particular time. So, this There is a second additional constraint. And then clothing potential shops, but again by
location and time. So, and those are the useful functions that we want to use, and we are registering them. But in order to overwhelm the the definition, I have these tons of additional tools that are kind of similar, but not exactly. That also registered in our configuration. So, if we have used and actually right now we're using the normal normal advisor, we would see all those tools.
Let's run this and just see how many tools we have registered up front and how many tokens we're going to consume with this. See, up front we have all these tools that we have available. They're already registered. I presume that LLM would be smart enough to figure out among those that they still not hundreds or thousand to to get to confuse the our model, but most likely
they Okay, so Yep, we got the current time. Then it's going to ask for for weather, and finally it's going to ask for the clothing and resolve the response. And we are going to see how many tokens we have consumed in this case. Something like Yeah, 40K 14K. Now, let's switch to the new strategy, and everything you have to do is just to use this alternative advisor.
Which builds on top of the previous one and try the same. And it's very interesting to observe what are the conversation and what goes back and forth between us. And so, we sent initially see we have only single tools pre-registered. The very first thing that LLM did our LLM did was to current date today. So, based on this query and our registered tool searcher, we actually the
user figured out that it can provide Yeah, somehow somehow even the weather matches a tool description into this category. We returned it both. So, the the assistant asked the weather the the time because it's prerequisite to ask the next functions. And then we provide the response. The assistant asked the weather information based on the location and the time that we have provided before returned from the previous
request. Then Yeah, we provided this response, and at this moment the assistant also realized that it doesn't have information about the clothing. So, it's going to perform a follow-up tool search tool request now for cloth shops. And here uh We smartly replied with this provided this information back. Now the assistant can ask this clothing and reply this with the same response. I'm just And we have Yeah,
half in this case half of the tokens that we've been used. So, it's very powerful way and advice advice way to use especially if you use a lot of tools and tokens. Explain about agents. This force and this is a pattern that actually was borrowed from product and called MemGPT later. How many of you have heard about MemGPT or later? in short, it was a very early
comer framework for for memory for for for many agent memory management. Very sophisticated. It used the same pattern for session, long-term memory stuff, but it comes with its very interesting ideas. And one of the ideas was that uh Let's say that you have a tool call, let's the weather one that has this location information, but you also would like to figure out why the LLM actually call
this tool when it calls it. How are You would like to get information why it's this tool was has been called. One of the common way and that's actually how they approach it, you're going to add additional parameter here inner thoughts with description, "Please provide information why I called this tool." So, when the LLM received this, it's going to fulfill this parameter, and you can actually use
it as a meta information to do something smart. Although it's completely related with the tool that you're calling itself. So, you're just using this as a hijacking to to pass this information, which is uh their approach, but it was kind of abusing the idea of tool itself. So, the what we did on our side in this particular technique is to augment. You can actually provide a very
simple proxy implementation that augments the the tool request and you can register random number of additional parameters on the way to the LLM. So, that for example, in this case you can add this inner thoughts parameter and the LLM for the LLM these two codes would look like you have valid tool call with all this description. I should it would be obliged to provide the information for
all fields here in order to call this tool. So, we would go on the way back our information about the reasons why this tool was called and we can either leave this parameter or as normally you would do, you're going to drop it but you can have a handler to actually act upon this. This is very common things you if you want to do some observability on
this. And in code So, behind this proxy the rest is the same tool tool tool request. And in code it would look something like You just can and this works perfectly fine with any tools, both local and and MCP tools. I'm looking for augmentor. And again, this is already in the spring spring code my off my spring on four. So, here is our original tool definitions. As
you know, single location. What we would like to inject additionally with this tool is this additional parameter inner thought see your step-by-step reasonings of why you are calling this tool and just for the randomness I also provided this parameter some confidence or additional memory thoughts. what you're doing under the hood instead of passing the original tool call Yeah, the definition of this class to the chat client,
you're going to wrap it first into this augmentor and say, "Okay, by the way, augment those tools but with this additional parameters." And under the hood this is yet yet another tool call provider. So, it's a normal abstraction of spring AI and you also can register your consumers that are going to act upon this special additional parameters like thinking inner thoughts, confidence, everything that we are asking
in addition. And if you run this Here we are. So, here is the response of reasoning. So, LLM reasoning the user is asking to uh for the current weather in Paris. This is a straightforward weather query blah blah blah blah. So, the confidence high. So, everything you might say, "But this is dynamic way you can actually enrich and provide some additional information while interacting with with with
the LLM agent. Most of the time it would be some additional observability. And here we are entering in another very interesting pattern in the same group of progressive disclosure. This is a topic in general, the the topic of disclosure. If you remember I mentioned about the rack and the context stuffing early on where you try to upfront preload your context with everything relative relevant to your question
hoping that this would be enough to yield the right response. So, you're doing the best manipulation in order to restrict or extract the context that makes sense for this question in order to augment this question in order to provide the right response but you did not evolve the LLM in order to make this decision. And this very often leads to overloading the context or sometimes not providing
the initial the the the required information although you did your best. So, the alternative to this is let's keep the context upfront as small as possible and let the LLM decide what to get next to put next in the context. So, the previous pattern turn to tool search tool was doing the same principle. So, you do not preload all tools definition upfront. You're letting the LLM to
decide which tool to add for any particular task. Agent skill very popular techniques lately. Actually, it solves the same problem. Try to solve the same problem for the context in general. So, do not preload your con important for you information but let the LLM what is important and what it needs for particular task to to do. And under the hood it is a straightforward concept. You can
provide the LLM with locate with information like what skills I have. Actually, that this additional information that you can plug into your context on demand is is is expressed like a skill name and description which is very similar like the tool hints the LLM when it should use ask you to get this additional information back into the context. So, and to this is the metadata of your
skill MD files and the context of the the mark markdown file itself is the actual information that you're going to plug into the into your context on demand. There is much more coming. Also, initially you're creating a catalog when you start your application with these names and description of all skills that you can have. Normally, it's a file systems with such structure. We also support James implemented
the agent jars where you actually can package this as a as a jars. And now Thomas actually has proposal I know on on the specs to introduce OCI as a packaging mechanism uniform. So, there's different way how you and there is a open PR on the agent skills that ask to provide a generic SPI to plug any possible this. So, it's interesting. It goes beyond the specification
but apparently there is a demand to have different way to express and to consume those skills. But the principle is the same. You're letting the LLM to know about the existence of these skills, what they can do and LLM can actually ask for more information. Spring AI implements the specification. It started again with cloud initial idea and then it was donated and there is a sort like
a foundation of specification that manages You can go here to find it and spring is one of the adopters of this I mentioned agent skills another way to wrap this bit and what it does underneath and this is another important bit to understand. It's nothing more than yet another set of tools. So, it is powerful concept but what you how you're implementing underneath you have a special
skill tools that actually can listen it it it it it advertise itself. It as an actually can list all available skills that have skills metadata that have been provided. And LLM can on demand ask for additional information with by hitting this skill tools and the skill tools is going to load the skill the rest of the body of skill itself. I'm going to run the demo in
a bit but before I get there this is the very basic idea of the skills. The skill itself can have a reference to other files and this is again falls in the concept of progressive disclosure. You do not try to preload the entire information in your skills. You just highlights and if there is some additional um branches of how the the LLM should follow, you can provide
this as additional markdown files and LLM is going to follow up and actually read these files. And what is scariest part in all this you can even provide us scripts that the LLM can use in order to fulfill and to support these skills that are running in your local machines. And for this you would have to provide tools like bash to enable this execution. And if you
do this, you definitely have to run your your your application in some sandbox or container environment. And this is exactly what I'm not going to do right now for my demo. the example the skills. Let's see first I have couple of predefined skills. This is one I downloaded from cloud I guess one of the default one. This is the format. See name, description. You can have some
additional metadata as well and this is the actual content of the skill. The skill itself can refer to some additional files and additional scripts. kind of community defined skills that is supposed to help you to generate some tutorials and it also is using a YouTube Python script transcriber in the process. So, let's run this and uh let's run this how you configure it in spring AI it's
yet another locations that you can pass or you can add a special dependency to a jar if you're agent jars capability. In this case this is the question. So, when you're building your application you're just defining yet another tools. This is the skill tools that I mentioned and it takes the list of directory where you have your you have your skill defined and it's entirely compatible with
any skills you can get out there right now. So, you it it can be very scary scary if you allow him to do everything in your machine. I did and yeah, it it actually runs scripts, generates JavaScript, compiles it, runs it. Yeah, it it it is quite impressive and scary at the same time. So, everything here out there it works. So, that's what we do. We are
actually these tools and also because we want to let it run shell scripts on our machines, we enable the shell tools. We also want to allow it to ask additional information which additional markdown files we also enable the file system tools. And this is unrelevant if it needs to get some additional information from internet this is also tools that we provide out of the box brave search
or So, let's run it and the question we're explain reinforcement learning in simple terms and even refer referring to some YouTube videos. And now I would expect now a lot of things to happen under the hood. Including executing this running this uh script. it immediately realizes or they have that it need this skill in order to answer our questions. So, that's what we pre-loaded this information and
now it's be back and forth. Okay, we already starting executing bash scripts. Come on. One of the benefits of using Spring AI to using agent skill is is that you can actually use it across various models in this case, I'm using we're using Anthropic, but yeah, OpenAI, Google Gen AI, Bedrock would work almost equally And eventually, it went it did this three transcripting, it run the bash
scripts, I believe, and we have the response. I I think you get some ideas about By the way, we're a very small audience, so if you have any questions, feel free to ask as as we go. So, I don't mind answering Another interesting uh uh pattern is called to do right, and it falls into the group of when you build a when you have a question or
a kind of complex um uh task to solve and you ask a question that requires complex pattern multiple steps to resolve, some of the agent models can get confused on the way to the answering, so performing too many intermediate steps and they can lose the track what actually was supposed to be done in certain points. So, in order to enforce them and to force them to actually
follow certain pattern structure, what you can do is to ask them to create a to-do list up front with certain structure, and then you can ask in the the same system prompt that you you define this logic, always perform a one step at a time, then the the items that that this to-do list is are is following have a very simple life cycle, pending, in progress, and
completed. So, you you can also enforce um in your system message that the LM should not progress to the next task in the to-do list before the previous one has been um completed. And in this way, if you have complicated task, you can enforce and make sure that the LM always follows and completes all all steps in the in the process. It's very simple pattern again, because
um from our side, we just introduce one dummy tool that even doesn't retain the state if you don't want it for from the use our standpoint, it's not really not important that much apart from, for example, visualizing what's happening as a steps. But for the LM, this really brings and enforce some sort of structure and it's using um the to-do right combined with memory in order to
ensure this progress on time. So, it's easier to show in in code than actually this diagram. To do right. So, that's what we have. It's yet another tool we're defining in our system. In this case, we are going also to define a memory to support and we have two code advisors. You you can see also that we're mixing and chaining two code advisors in order to fulfill
some greater goal. And in this case, um okay, let's let's we have very simple request response And I think I have some challenging question here that hopefully would force the LM to perform multiple steps. I knew it. Good luck. Okay, so now you see actually it goes and and what I didn't show, I also plugged some UI callbacks that I'm using just to visualize what's happening. So,
it started with first first task. It completed it. It moved to the second And when it's going to complete it, it is going to So, this is a technique to ensure that the LM actually always going to do the task in the right order and it's not going to skip something on the way out. And again, this is a pattern that I actually borrowed from the cloud
code itself implementation. It was something Interestingly, the last version of of the cloud code actually moves away from this pattern because they actually re-implemented some of this logic in their new task management mechanism, but the idea is the same. You are actually [clears throat] forcing the LM to follow certain pattern not forget the the steps and always move to the next step before after the previous has
been completed. And here we are kind of stuck. Uh no, actually we Oh, this is the old demo. Sorry. Let's me remove these bits. So, next. This another simple uh pattern which does something similar. Very often the LM are going opinionated. If you ask a complex any question, they would tend to make assumption and go forward. And once they moved forward, it's very hard to force them
to to to come back and to actually correct what they um you you intended them to do. What you can make in order to improve this interaction I mean yeah, it could be some sort like it legitimation. You can ask them or in um in ask the LM to ask for additional questions, clarification question before actually it makes the final decision. So, um in code again, it's
yet another tool that you implement with a this special description saying that telling the LM, "By the way, if you're not sure about how to proceed to have multiple choices, don't make opinionated decision, ask us for for details." And there is a certain format that the LM can ask you, usually a multiple choice with a um also free text. And uh Spring AI provides out of the
box uh uh handlers. You you you you you're supposed to plug in the handler. So, Spring AI provides out of the box uh handler for the command line implementation, but if you have some special UI framework, you would have to provide this handler yourself. And let's see again how this looks in code. Again, this is yet another tool. Ask user question. We are registering in our system.
We have the two code advisors. We have the memory. And again, the same loop. Let's run this. Should I visit next? Without adding this tool, most likely the LM is going to make some assumption and give me some suggestions based on no context at all. Now, because we have these bits, we're going to get some uh reque- question for quali- Okay, nature and outdoor, let's say. Warm
Mediterranean, okay. Luxury. Oh. Okay, let's Maybe. Okay, that's And now apparently, uh door those were pre- the the initial Oh. What I did. Maybe I should have picked luxury, I Others. So, this is slightly different question. I didn't mention you, so I think it would we would get different set of responses. Okay, culture. Warm. Ah. Okay, let's reduce our set. So, but you Hopefully now we would
provide us with response. While we we get there, I'm going to touch upon yet another um pattern and I think we're going to to stop there. It's called sub agents. Okay, we have the response here. So, what are the suggestion? Spain, okay. Malta, not bad. Italy, okay. I think we're in a good company. Uh so, uh sub agents. This is yet another If you remember, we already
uh context um um progressive disclosure and how to optimize the context with the tool search tool, with agent skill that helps you to segregate the context before or actually ask the context on demand. Sub agents are another techniques that tries to manage and to keep the context clean. And the idea is that if you have a complex task, in order to solve the complex task, the LM
would have to solve a lot of small sub tasks. In order to solve these sub tasks, very often it's going to use tools, um additional tools, additional skills, and it's going to pollute your main agent or lead agent context, which would decrease the chance and the the ability of this agent to solve and to provide the respo- right response. The solution is kind of straightforward. Let's run
these sub tasks in their own isolated context. And this is the idea of the sub task. Under the hood, it's yet another task tool that you can be configured to run um task which are defined in markdown very similar like agent skills. So, it's a front matter metadata, name of the task, the description what it does. You can actually have dedicated model. Very often the subtask would
run very small faster model dedicated and especially for this particular task. And only the response they run in the isolated context and only the response the result of this task execution subtask is also agent execution is going to be returned and added to the original context. Spring here extend this concept practically in addition to this local definition. You can actually plug and define eight way agent description
as And um I maybe have Oh, this is indeed the diagram. You have in them we Yeah, I will share the source code from this and many other demos. You can run and then this is one of the more extended one. We wouldn't have I wouldn't have time to to to get you Just want to wanted to point out that the concept of this advisor that we
discussed is to to recap. We built everything with advisors with one small exceptions the two co-advisor, which also relies on the ability of the I want to execute tools. So, two co- two advisors practically advisors and the tool support is everything you need to implement all of these patterns that we saw I demonstrated so far. And then it's very important to order I mean right order. Here
is the last thing I'm going to share. This was the two co-advisor and the memory. So, with the two co-advisor as an advisor, you can actually use the memory to intercept the input and output. And this is a concept of the of the of the two request and response, something that was not possible before with the old implementation of the co- handling. And what is important is
the order. See, we In this case, in order for this to happen, the your memory advisor should be inside your two co-advisor. If you change the order, it's still going to work, but it will be the old behavior. The memory is going to also to only to is going only to memorize your original request and final response. With this, yeah. Uh I'm open for questions if you
have. Actually, there is no questions. You can send the questions and I'm open for discussion afterwards. So, thank you very much for the patience.
More from this event
See all 38 talks →
Spring I/O 2026 Keynote
1:08:44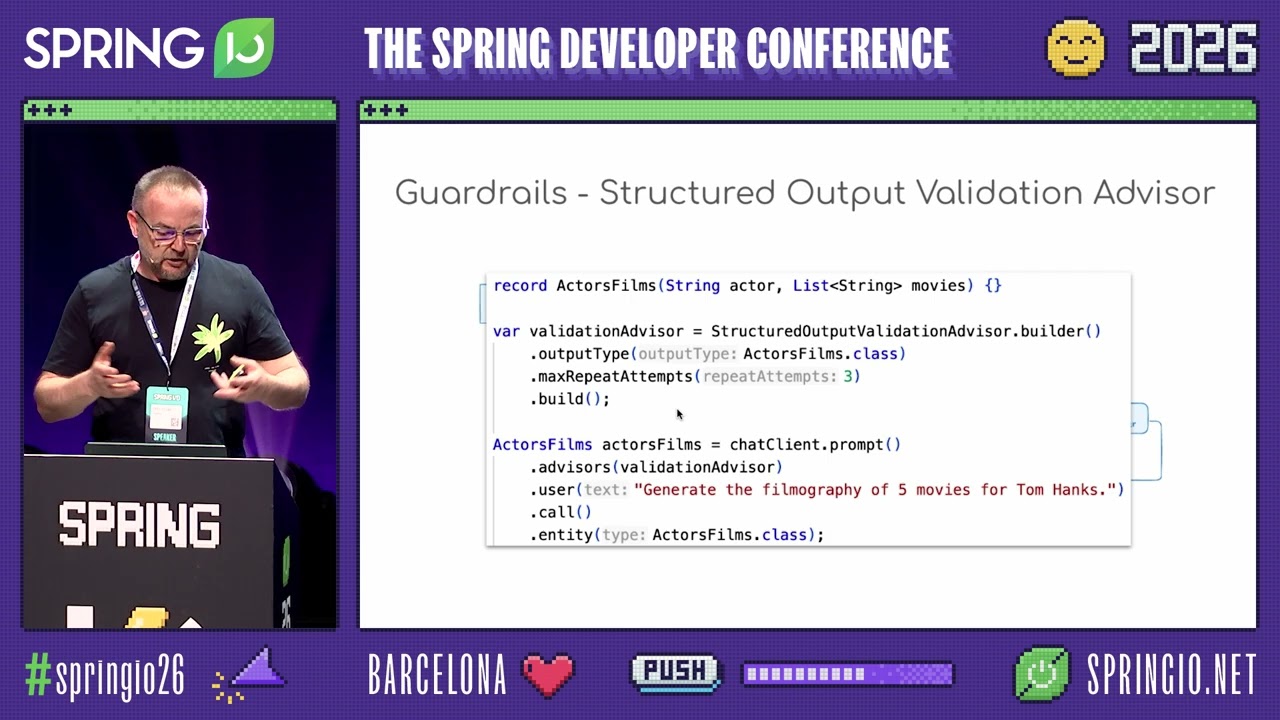
The Spring AI Ecosystem in 2026: From Foundations to Agents @ Spring I/O 2026
43:39
Breaching LLM-Powered Applications: Overcoming Security and Privacy Challenges by Brian Vermeer
48:40
New in Spring Security 7: MFA, OAuth2 and more by Daniel Garnier @ Spring I/O 2026
46:43